Ryan Neufeldt
Conversation Designer · AI Systems Design
I design conversations that make AI useful, trustworthy, and honest about what it doesn't know. Four years running an enterprise support bot from the inside out at Recharge. More recently, building one from scratch at the model layer, designing the evaluation systems and behaviors that make GenAI safe to put in front of real customers.
Designing for What the Model Doesn't Know
Remi / Recharge's GenAI Customer Support Agent
Context
Recharge needed to ship a next-generation GenAI support agent to replace a rule-based system that had reached the limits of what logic trees could handle. The model would be smarter and more flexible, but it introduced a problem rule-based systems don't have: confident wrongness. A bot scripted to say "I don't know" does so reliably. A language model doesn't always know what it doesn't know.
The deeper challenge was measurement. AI judges can evaluate whether a response was accurate, grounded, or helpful. But that data alone doesn't close the loop. You need a system that can act on what the judges find, in a way that's safe enough to trust.
There was a second, quieter problem. If the system that proposes an improvement also decides whether the improvement worked, the evaluator becomes part of the failure. I designed the improvement loop so no part of it could be the sole authority on whether its own fix succeeded.
The evaluation architecture was heavily influenced by Anthropic's work on AI-agent evaluation, particularly the January 2026 “Demystifying evals for AI agents” guidance, along with other Anthropic evaluation and adversarial-testing work.
The Design Problem
How do you ship a GenAI agent that's safe enough to put in front of real merchants, without making it so cautious it becomes useless? And once it's live, how do you improve it continuously without risking regressions that undo what's already working? The standard answers (constant human review, confidence thresholds alone, or blanket disclaimers) all trade capability for safety in ways that defeat the point.
Design Insight
"Uncertainty isn't a failure state to hide. It's a signal worth surfacing. The design question is who sees it, in what form, and at what point in the conversation."
Design Approach
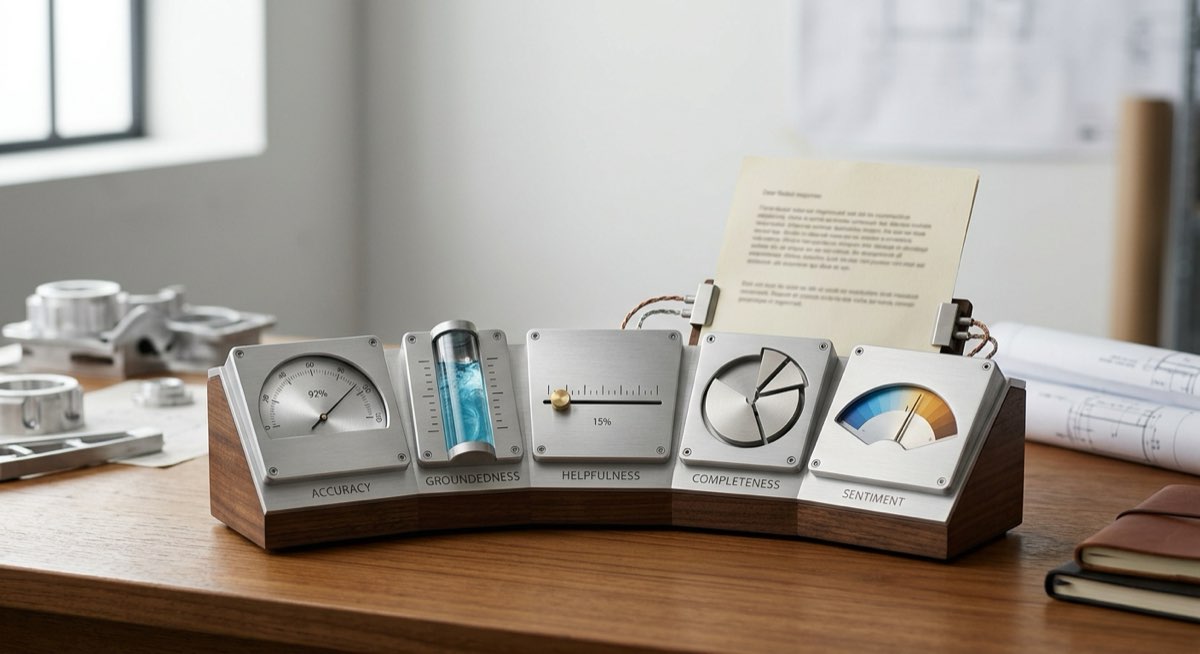
01 / Evaluation
Five evaluation dimensions, never combined into one score
I built evaluation across five separate axes: Accuracy, Groundedness, Helpfulness, Completeness, and Sentiment. A response can be factually accurate and completely useless to the person reading it. Collapsing them into a single quality score hides exactly the kind of failure you need to see.
02 / Calibration
Weekly human calibration with a coaching mode designed for speed
I built a lightweight review interface so the support team could coach conversations efficiently. Binary buttons across five dimensions, Haiku-drafted Issue/Solution summary for reviewer confirmation.
03 / Reliability
Inter-annotator agreement as a quality check on the evaluators themselves
I used Cohen's Kappa (two reviewers) and Fleiss' Kappa (the full group) to measure whether the team was applying the same standards conversation to conversation. Inconsistency in the reviewers corrupts everything downstream.
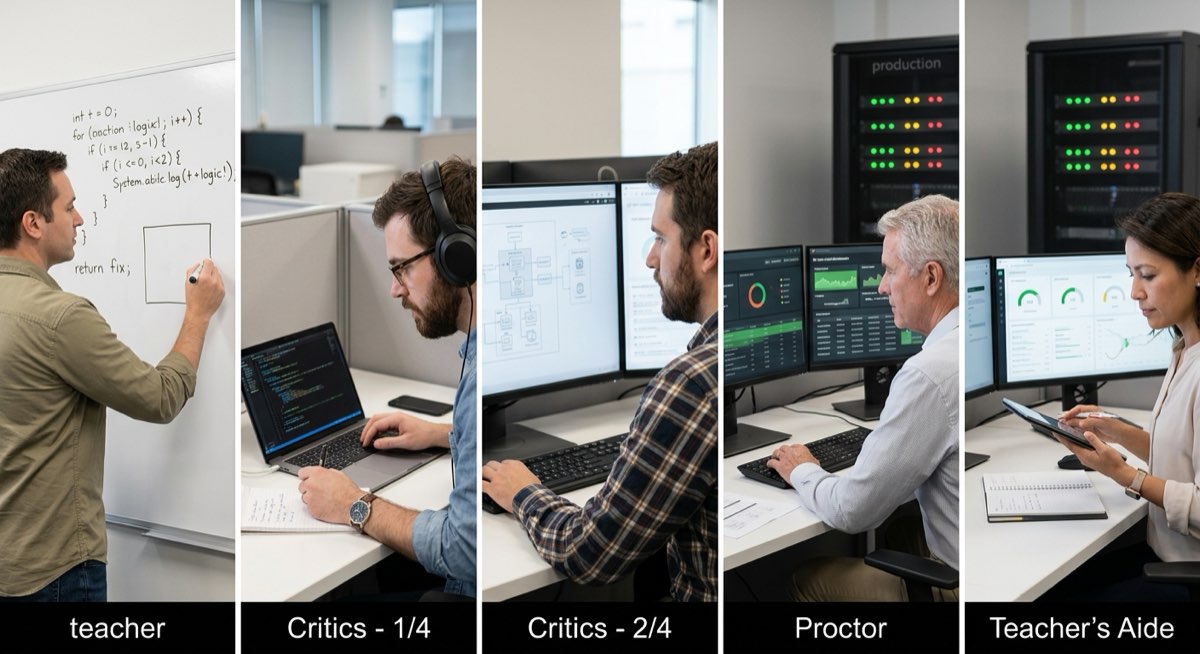
04 / Pipeline
An adversarial pipeline, so the system can't grade its own homework
A Teacher proposes a fix and tests it five times before and after, each run in a fresh session. The Proctor then tries to break both the proposal and the evidence: was the diagnosis right, does the fix address it, what else could it break, is it passing for the wrong reason? A Teacher's Aide checks what was predicted against what happened and runs broader regression checks. A person makes the final call.
05 / Architecture
Source of truth first, hardcoded answers never
The bot's first answer should always come from the current knowledge source, not from what it was programmed to say. Product drift is inevitable; the architecture had to treat the knowledge base as the authority.
06 / Documentation
DOM-level documentation as an infrastructure layer
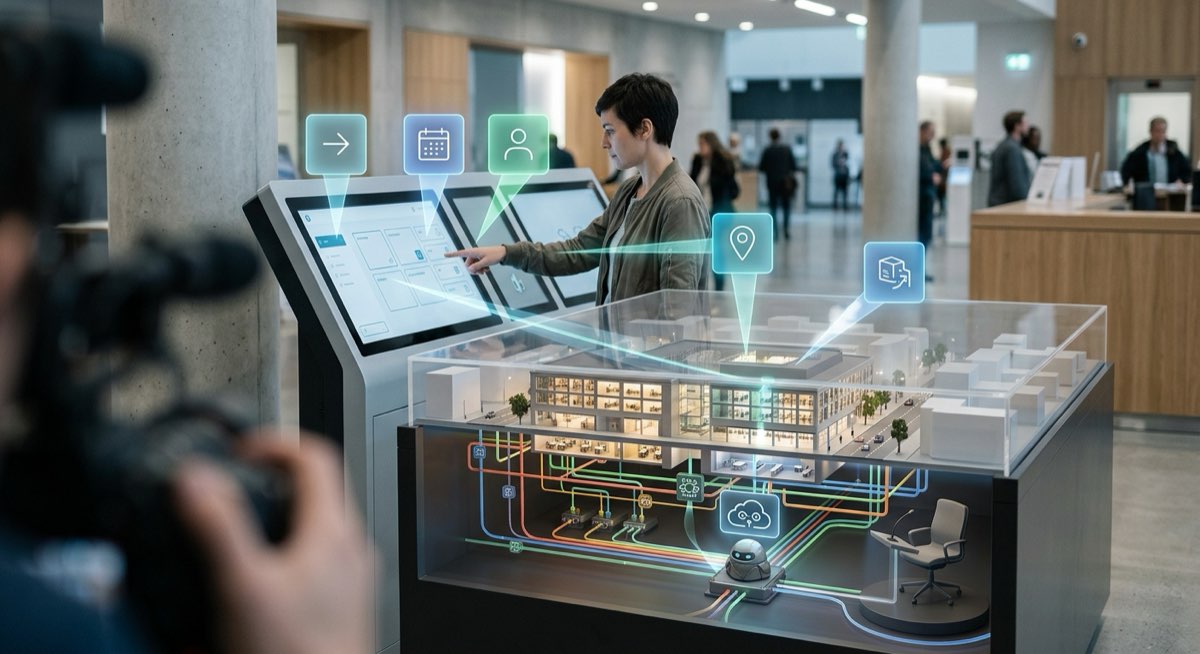
Page-level documentation written from the user's perspective: the exact labels they see, the actions available to them, the context the bot needs to answer questions about that page correctly.
Self-Healing Pipeline: Evaluation to Production
Five runs was the practical sweet spot we found by testing: one run was too noisy, and returns diminished after about five. It was an engineering tradeoff, not a claim of statistical proof.
In Practice: What the Evaluation System Catches
Orders sometimes fail to process due to payment issues. Check that the customer's payment method is current and valid. You can ask them to contact their bank if they're seeing an unexpected charge. If the problem continues, contact Recharge support.
A charge on a customer's card statement and an order in Recharge are not the same event. Go to the customer's profile, open the Errors section, and click the failed charge. The Message field shows the specific decline reason.
If you see "Do not honor": Hard decline. Recharge does not retry. The customer needs to contact their bank or update their payment method.
If you see "Insufficient funds": Soft decline. Recharge retries automatically. The order appears once a retry succeeds.
What the customer sees is likely an authorization hold. It clears within a few business days when the charge fails. Not a double charge.
Outcomes
Four Years of Conversation Architecture
Ada-Powered Support Bot / Recharge / Shopify Ecosystem
Context
Recharge serves thousands of subscription-commerce merchants on Shopify. The surface area of what the support bot had to understand was wide. Billing configurations, subscription logic, API integrations, and edge cases specific to how each merchant had set up their store. Merchants customize extensively: the subscription widget embedded in their Shopify theme, the styling and flows they build around product swaps and cancellation, the automation rules they configure for billing cadence, prepaid plans, and dunning behavior.
A bot that can answer generic subscription questions is relatively easy to build. A bot that can answer questions about how a specific merchant has configured their store is a different design problem. I owned the full conversation design for Recharge's Ada-powered support bot for four years: strategy, architecture, launch, and continuous improvement.
 Four years of conversation architecture
Design Insight
"The conversation architecture is only as good as the knowledge it draws from. Designing the bot and designing the knowledge base are the same job. Most teams treat them as separate ones."
Design Approach
01 / Retrieval
Rewriting knowledge for AI retrieval, not human navigation
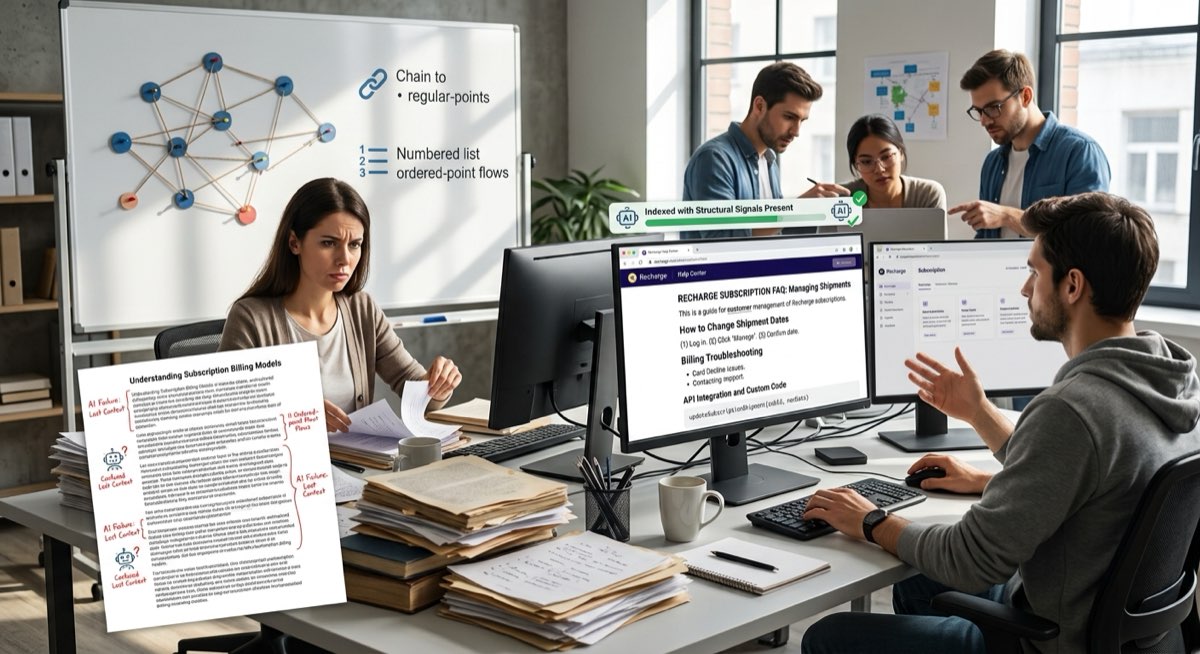
Regular bullets tell the model items are linked. Numbered bullets tell it order matters. Multiple unstructured paragraphs risk losing context during retrieval. Bold, headers, and code formatting act as structural signals. These aren't writing conventions. They're closer to programming.
02 / Framing
Reframing content around user questions, not product features
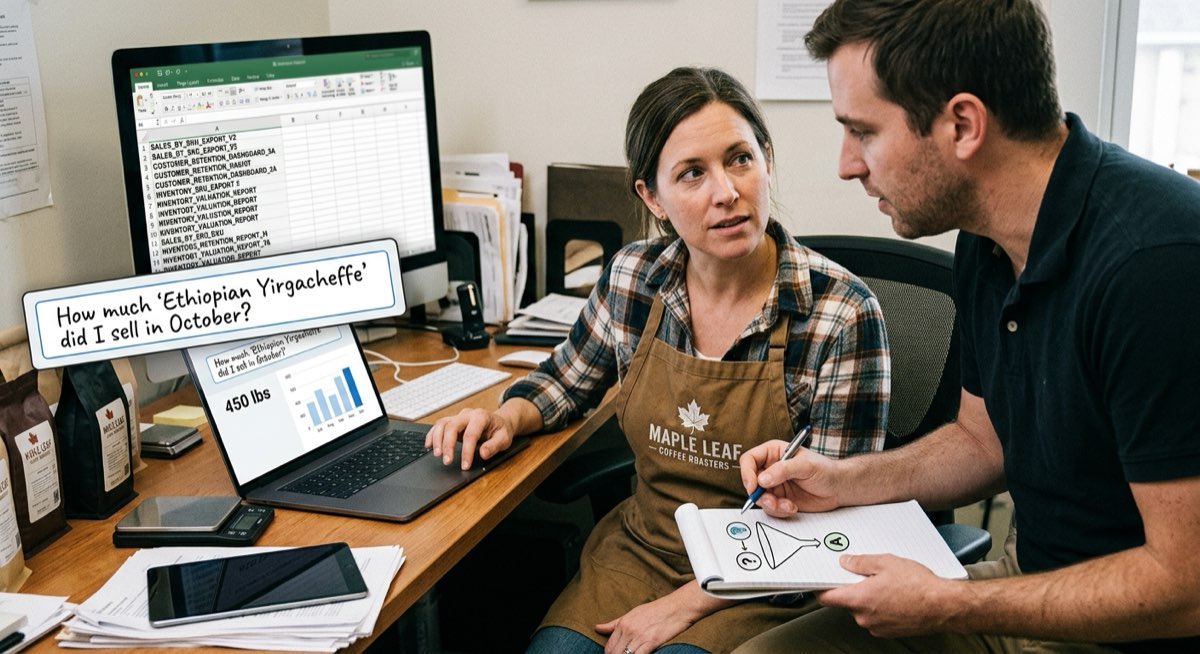
Recharge's analytics documentation listed export report names. Merchants don't search for "analytics dashboard." They ask "How much of X product did I sell between date1 and date2?" I rewrote those articles to answer the actual question. That work also became the evidence case for building natural-language reporting.
03 / Coverage
Augmenting the knowledge base beyond Recharge's own documentation
For order errors, the useful information lived in Shopify's and Stripe's own documentation. I incorporated their error code meanings so the bot could give a specific answer ("contact your bank regarding rejection code 51") rather than a generic one.
04 / Design
Short, focused skills over comprehensive ones
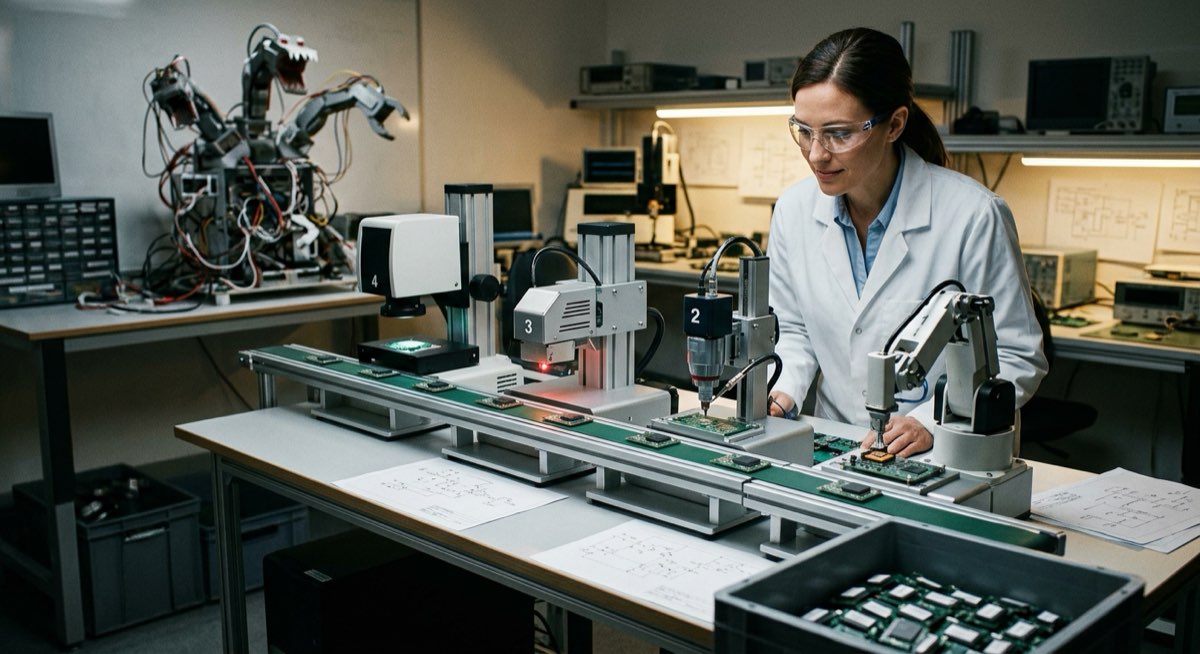
Long skills go off the rails. Each skill should do one specific thing well. Chaining focused skills is more reliable than trying to anticipate everything in a single dense definition.
05 / Automation
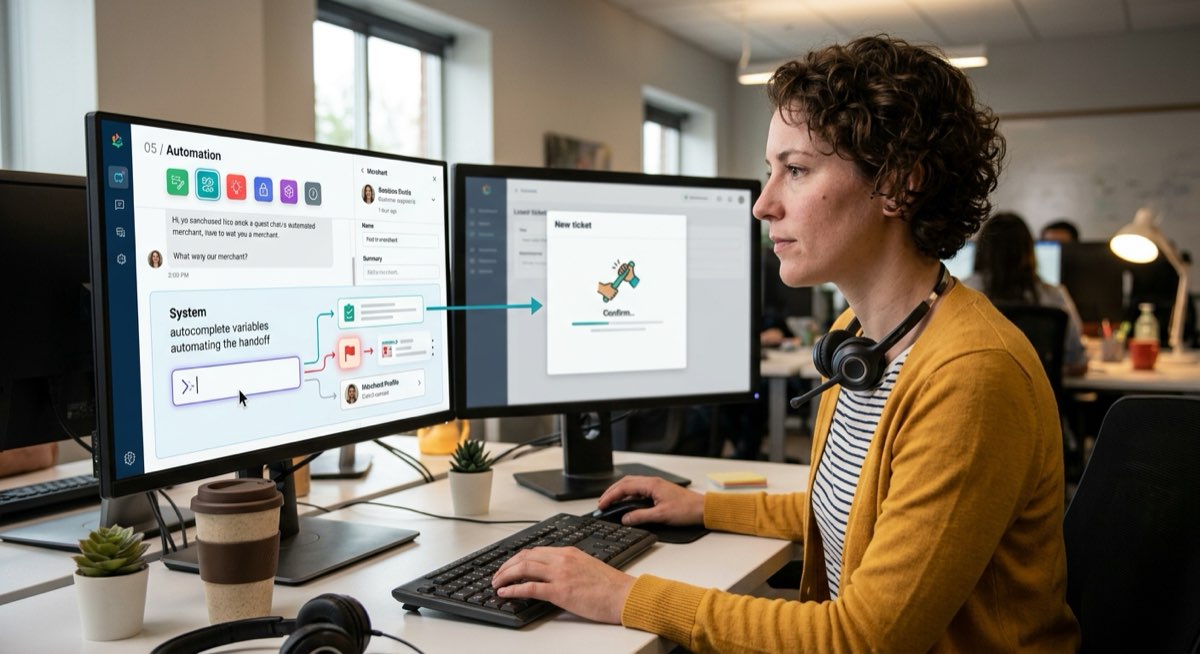
Using Autocapture variables to automate the handoff
Autocapture variables were the generative feature inside Ada's declarative bot: they used AI to read what the merchant said and fill in the details. Before that bot had playbooks, I stretched them, through prompting alone, to work as playbook-style skills, something Ada had designed only for its generative product. The escalation flow summarized the merchant's issue, auto-classified priority, and pre-populated context for the agent, without any additional tooling.
06 / Focus
Analytics-driven human focus
Dashboards tracked which skills were driving the most volume and pain: bad sentiment, low resolution, repeated contacts. That data drove the weekly improvement list. Human attention went where it had the most impact.
Conversation Architecture: Intent Routing
In Practice: Knowledge Article Before / After
Merchant question: "A customer's charge failed. How do I find out what went wrong and what to do next?"
Available exports: Customers, Orders, Subscriptions, Charges, Addresses. Go to Tools & Apps → Exports to access them. Select an export type, set a date range, and click Export data.
Use Charges - error, not Orders. A charge is an upcoming transaction; an order is only created after a charge processes successfully. If the charge failed, there is no order to find.
Check
error_type and error_message. Hard declines (do not honor, stolen card) require the customer to update their payment method. Soft declines (insufficient funds) retry automatically on Recharge's dunning schedule.The same rewrite principle applied across Recharge's entire help center: stop naming features, start answering the question the merchant actually arrives with. This matters for the bot and for merchants searching via Google or AI tools directly.
Outcomes
How I Think About Conversation Design
Words as interface
The words in a conversation are the UI. Clarity, tone, and precision matter as much as visual design decisions, and often more, because bad copy in a dialogue has nowhere to hide.
When I rewrote Recharge's export documentation from a list of report names into answers to actual merchant questions, the bot's responses changed immediately. The writing was the design change.
Failure modes first
I design the failure states before I design the happy path. What happens when the model is wrong? When the customer is frustrated before they type? These aren't edge cases: they're the test of whether the design actually works.
The first design question for Remi wasn't "how does it answer well?" It was "what does it say when it's confident and wrong?" The evaluation system, the five dimensions, the self-healing pipeline: all of it came from answering that question first.
Pattern over script
A response scripted for one scenario breaks the moment the scenario shifts. A pattern designed to handle a class of situations stays useful. I build for reuse, not one-off coverage.
In the Ada escalation flow, a single Autocapture variable pattern could summarize the merchant's issue and pre-classify the ticket's priority. One pattern across every escalation type, not a script for each one.
Trustworthiness by design
A customer's trust in an AI conversation is fragile and cumulative. Designing for trust means designing honest acknowledgment of uncertainty alongside confident answers, not hiding the seams.
Remi's evaluation keeps Accuracy and Groundedness as separate dimensions because a response can be accurate but not grounded in what the system actually retrieved. An answer drawn from memory rather than the current knowledge source is the specific failure mode trust requires you to prevent.
Open to senior conversation design and AI experience roles. Remote-first, based in Kitchener, ON.
Get in touch →This portfolio was built with AI assistance and reviewed by me.